AI Coding Agents on a Live Game: Faster, Inside Guardrails
Claude Code and Codex on a live game: one shared rule file, scoped skills, hooks and CI that check, and explicit approval before anything touches production.
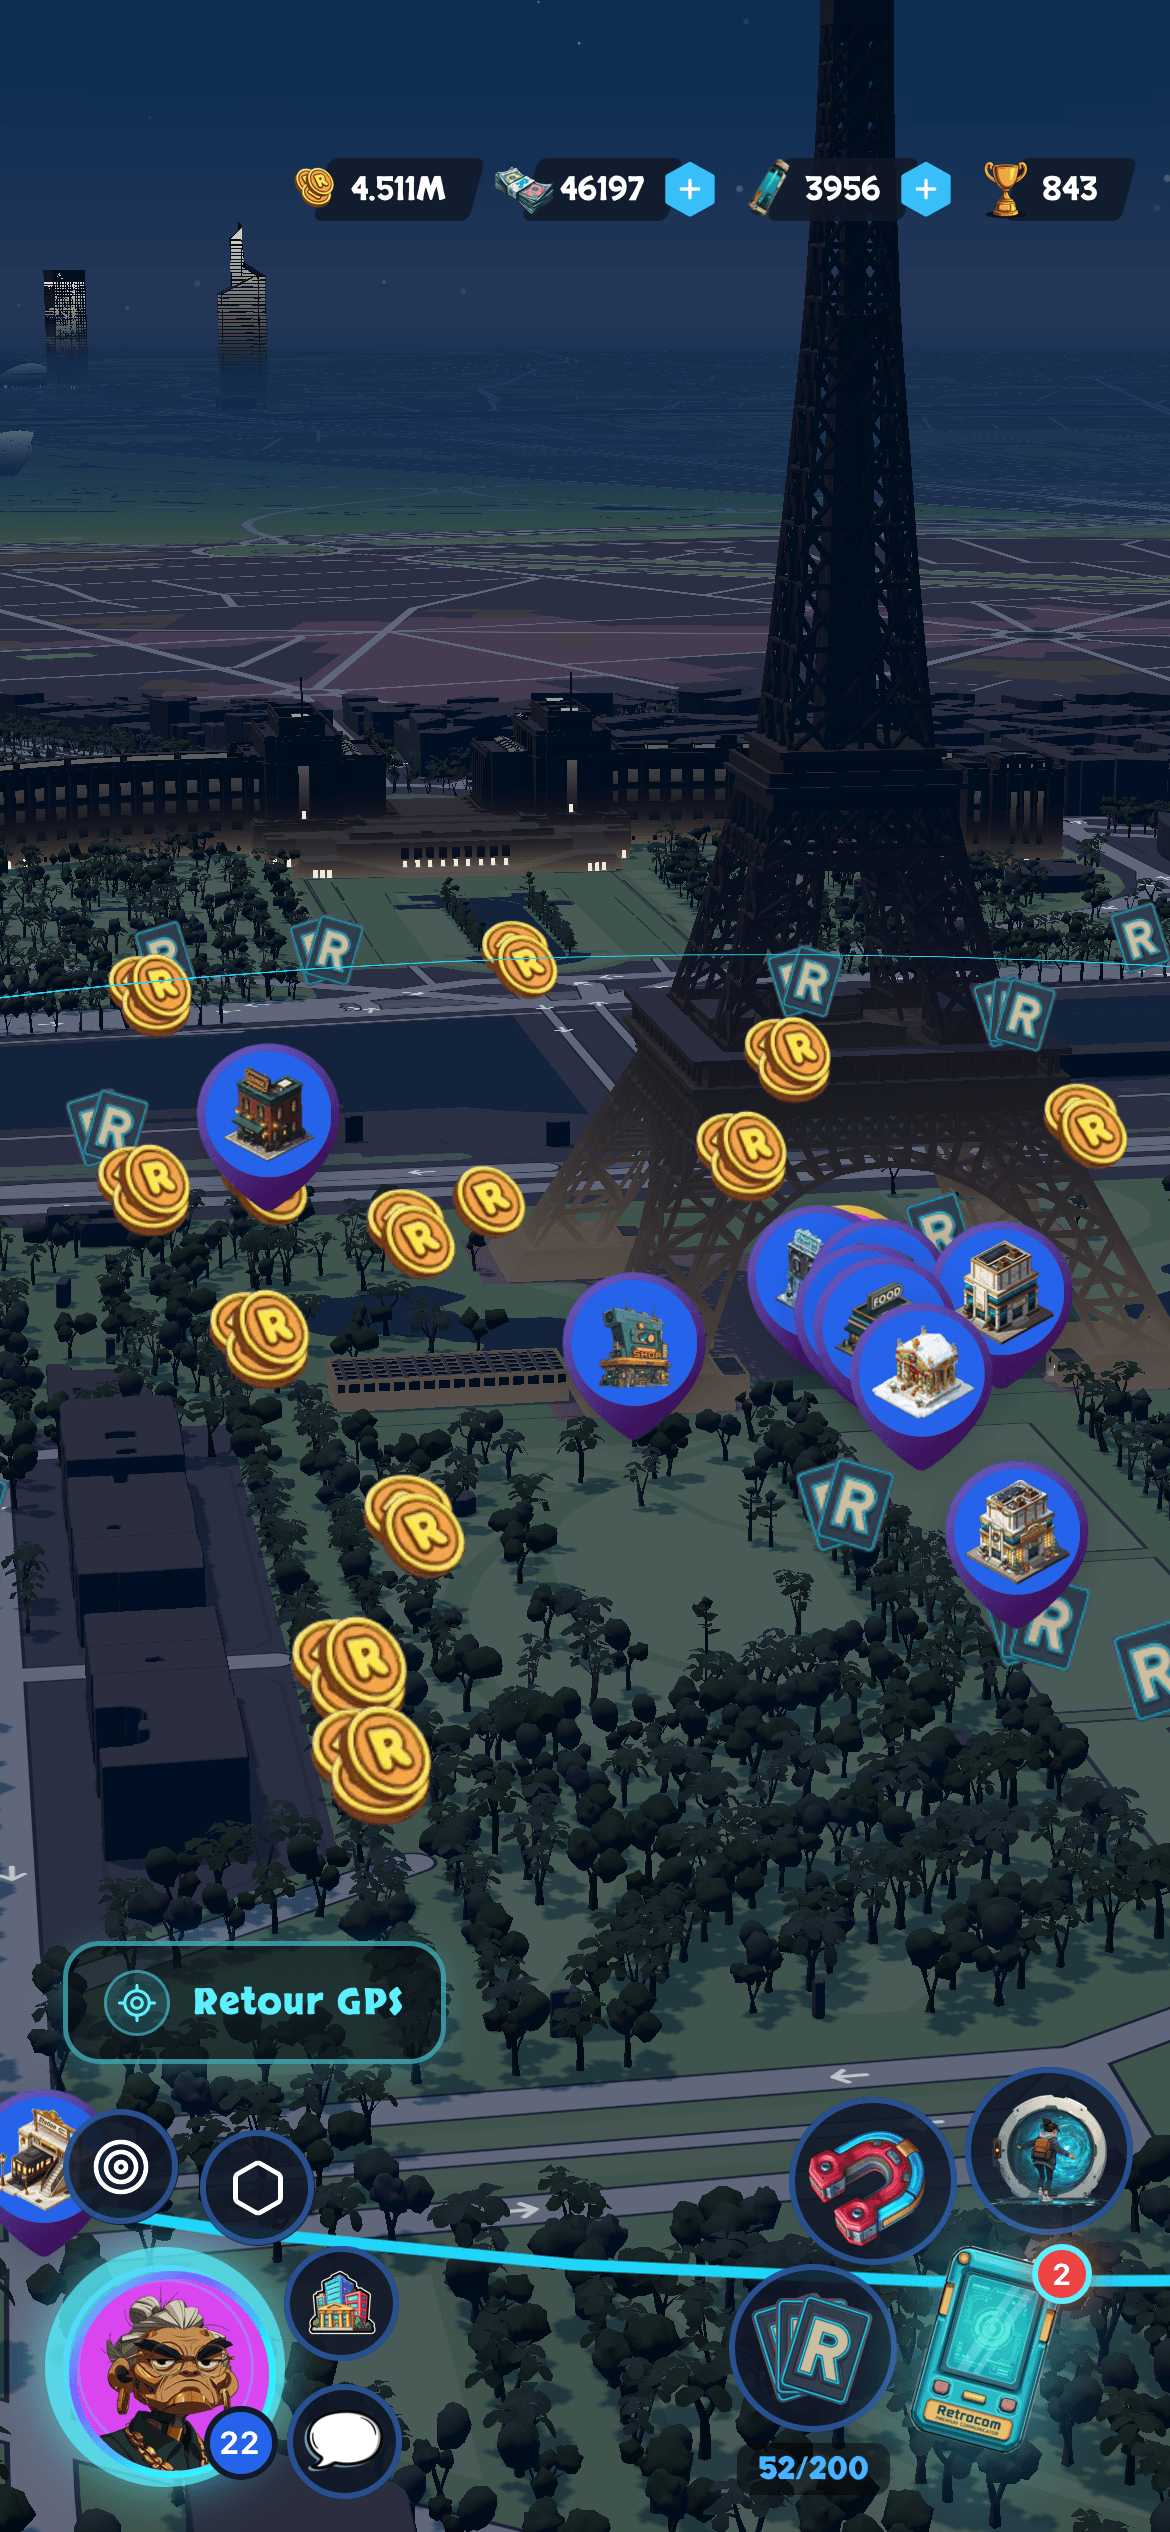
Retropolis is a live game. Players claim real buildings that pay out every hour, run contracts and lose coins to each other's Hold-ups, and a season runs on a calendar we don't get to move. Behind that sits one monorepo: a Go game server, an Expo mobile app, two Next.js sites (this one and an admin console), Firebase jobs, a Discord bot, an admin CLI, and the Remotion project we use for our promo videos.
A small studio can't staff all of that. AI coding agents, mainly Claude Code with Codex alongside, let us keep the pace: our development branch took about 670 commits in the last three months. That speed is real, and so is the blast radius. An agent that misreads a database transaction can pay a reward twice to every player. This post describes the guardrails we put around the agents, in the order we would set them up again.
1. One instruction file, every agent
Each agent tool reads its own instruction file. Ours all read the same one. AGENTS.md holds the repository rules, and CLAUDE.md is a few lines that import it and point to the Claude-specific extras. When a rule changes, it changes once.
The rules are the ones a new hire would need on day one, written as invariants rather than advice:
- Product. Never hardcode a player-facing string. English is the source, and French, German, Spanish and Italian stay aligned. Before naming a game concept, check the glossary, so the same thing never gets two names. A gameplay change updates its feature doc.
- Server. Keep HTTP handlers thin. In a database transaction, do every read before any write, reset any state the transaction function captures (the database may retry it), and run external side effects such as push notifications only after commit. Background jobs must be idempotent.
- Code style. Prettier and
gofmtare canonical, on changed files only.
The transaction rules exist because the failures are silent. A Firestore transaction function can run more than once under contention. If it appends to a list declared outside the function, a retry appends twice and nobody notices until the economy drifts. Writing the rule down helped; making it fail a test helped more. Our mock transaction enforces the real database's semantics, so a write before a read fails in unit tests instead of in production.
2. Load only what the task needs
A long instruction file gets skimmed, by people and by models. So the root file stays short and the specialist knowledge lives in skills: thirteen project skills such as go-server-dev, mobile-dev, translations, data-migrations, release-ops and promo-videos. Each starts with a one-line "use when" trigger, written in English and French because we prompt in both.
Large skills are split into a short SKILL.md and reference files the agent opens only when the task needs them. The promo video skill went from 28 KB to under 6 KB that way. One small rule saves a lot of drift: skills and docs cite code by file path and symbol name, never by line number, because line numbers rot within a week.
3. Machines check, prompts only remind
Instructions lower the error rate. Checks catch what's left. We stack them so that each one is cheap where it runs:
- After every edit. A hook compiles the Go server whenever an agent edits a Go file and blocks the agent if the build breaks. Some types are mirrored by hand between Go and TypeScript, so editing one side prints a reminder to update the other.
- Before every commit. A pre-commit hook compiles the staged Go modules, runs the test suite, and checks that the Discord bot's knowledge index matches the docs. Our bot answers player questions from an index of our feature docs, so a stale index means wrong answers on Discord.
- On every push. CI runs TypeScript type checks and tests across the workspace, ESLint, Prettier,
go vet, and the Go tests with the race detector against a real PostGIS database.
Cleanup tools follow the same logic. Dead-code detectors (knip for TypeScript, deadcode and staticcheck for Go, an unused-translation-key scan) produce candidates, and the rule is to never delete on a detector's word alone. Every exception kept in the knip config carries a comment saying why it is a confirmed false positive.
4. Permission is per action
The rule that matters most is short: production, deployment, merge and live-data actions need explicit approval, for that action. Approval to implement a feature is not approval to merge it, and approval to merge is not approval to deploy.
That shapes the tooling around it:
- Pushing our main branch deploys the game server immediately, so agents never push it.
- Data migrations are written to run as a dry run by default. They apply only after a person has read the dry-run output and said so.
- The agent's pre-approved commands are a short, committed allow-list of read-only and check commands: tests, type checks,
git log,git diff, search. Anything else asks.
5. One human author
Every commit has one human author. Early on, commits also carried a co-author trailer naming the model; we dropped it at the end of July 2026, and no commit since carries tool attribution. A trailer suggests shared responsibility, and there is none. Whoever commits the change answers for it.
6. Verify in proportion
Agents love to run everything. A full build on a docs typo wastes minutes; skipping the one test that covers a payout wastes much more. Our verification guide lists the checks per surface with their real durations (the server checks take about fifteen seconds warm), and the instruction is to start with the smallest check that exercises the changed path and its important failure case, then report exactly what ran. "Tests pass" without saying which tests is not a report.
The lightest process by default
Most requests are small, and a ceremony around them is waste. By default an agent works in the current checkout, implements what was asked and verifies it. No ticket, no branch, no pull request unless asked.
For bigger work there is a heavier lane, used only on request: one Linear ticket, one git worktree, one visible agent session, a pull request that keeps every section of our template, a self-review against our review checklist, and a merge only after the named pull request is explicitly approved.
Where the agents help, and where they don't
They help most with breadth. One gameplay change can touch a Go type, its TypeScript mirror, five translation files, a feature doc and the Discord bot's index. An agent that knows the rules does all six; a tired developer forgets two. They also made tools we would never have found time to write: our Remotion video pipeline and the in-house studio that builds our store listing both exist because an agent could write most of the code while we decided what they should do.
They help least with taste and truth. Left alone, a model writes generic game text, so the game's writing follows a voice guide and gets rewritten until it fits the world we described in Every Mechanic Tells a Story. Generated art has a look players recognise, so our videos and store pages only show the real game. And a model will state an invented fact with total confidence, so anything that goes public is checked against the code first. That includes this post.
If you want to try this on your own project
- Write down your invariants before you write prompts. If a rule matters, it belongs in a shared file every agent reads.
- Turn the rules that cost the most when broken into checks: a hook, a test, a CI job.
- Make permissions per action. Most of the risk sits in the last step, not in writing code.
- Keep the default process light and the heavy process opt-in.
If you'd rather see what all this ships, install Retropolis and read what kind of GPS strategy game it is.